


Choosing the model with the highest public benchmark score is becoming one of the least reliable ways to choose an AI model for production.
The Stanford AI Index 2026 found that AI capability is advancing faster than many benchmarks can measure it. Frontier models gained around 30 percentage points in a single year on Humanity’s Last Exam, while several evaluations designed to remain difficult for years are already saturating within months. Stanford also reports invalid-question rates as high as 42% on some widely used benchmarks and increasingly narrow performance gaps among leading models.

That creates a practical problem for enterprises. A model can lead a leaderboard and still fail your customer-service workflow, retrieve the wrong policy, miss manufacturing defects under your camera conditions, or make unacceptable tool calls inside an AI agent.
AI Model Evaluation should therefore answer a business-specific question: is this model, inside this application and under realistic operating conditions, good enough to deploy?
That requires more than accuracy. Enterprises need to evaluate quality, reliability, safety, latency, cost, retrieval, tool use, edge cases, and the impact of the complete AI system.
Let’s dive deeper into how AI Model Evaluation works, which metrics matter, how to build an evaluation pipeline, and how to turn model testing into a production discipline rather than a one-time benchmark exercise.
What Is AI Model Evaluation?
AI Model Evaluation is the structured process of measuring how well an AI model or AI-powered application performs against defined requirements.
For conventional machine-learning models, this may involve familiar statistical metrics such as precision, recall, F1 score, mean absolute error, or AUC. Generative AI introduces harder questions because many outputs have no single correct answer. Evaluation may therefore combine reference-based metrics, human judgment, model-based graders, task-specific rubrics, adversarial testing, and production feedback.
The key distinction is between model capability and application fitness.
A general-purpose LLM may perform strongly on reasoning benchmarks, yet an enterprise application can still fail because:
- The retrieved context is wrong.
- The prompt produces inconsistent output.
- The model ignores an important business rule.
- Tool selection fails on edge cases.
- Latency exceeds workflow requirements.
- A cheaper model achieves the same business outcome.
- Accuracy drops for the company's actual data distribution.
A useful evaluation program measures the behavior that matters to the application rather than relying on a universal score.
Public Benchmarks Are Useful — But They Are Not Your Acceptance Test
Benchmarks remain useful for narrowing a model shortlist. They can reveal broad capabilities in coding, reasoning, language, multimodal understanding, or mathematics.
They should rarely make the final production decision.
The problem is partly benchmark saturation and contamination. In July 2026, NIST launched its Artificial Intelligence Technology Evaluation program, which evaluates models in a sequestered environment using blind data specifically to reduce train/test contamination and support more objective testing.
For an enterprise, the more important limitation is simpler: public benchmarks do not represent your workflow. A financial document assistant may need 99% extraction accuracy on a small number of regulated fields. A customer-support model may need reliable refusal behavior when information is missing. A manufacturing vision system may prioritize zero critical misses over average classification accuracy. Those requirements do not appear on a generic model leaderboard.
Our rule is: Use public benchmarks to discover candidates. Use your own evaluation set to decide what ships.
The Three Layers of AI Model Evaluation

A mature evaluation strategy should work across three layers.
| Evaluation layer | Main question | When |
| Model-level evaluation | Can the model perform the target capability? | Model selection / experimentation |
| System-level evaluation | Does the complete AI application perform the workflow correctly? | PoC / development / release |
| Production evaluation | Does performance remain acceptable with real users and data? | After deployment |
1. Model-Level Evaluation
At this level, isolate the model as much as possible. Compare candidate models on a controlled dataset using the same prompts, temperatures, tool definitions, or image inputs.
This helps answer questions such as:
- Which model performs best on the task?
- Does a smaller model meet the quality threshold?
- Does fine-tuning improve the baseline?
- How much quality is gained for additional inference cost?
- Does a model upgrade introduce regressions?
Model-level testing is useful for architecture decisions, but it is still only the first layer.
2. System-Level Evaluation
Most production failures occur above the model layer.
A RAG assistant includes retrieval. An AI agent includes tools, permissions, orchestration, and state. A document-processing solution includes OCR and preprocessing. The entire execution chain must therefore be tested.
Input
│
▼
Preprocessing / Retrieval
│
▼
Prompt + Model
│
▼
Tool / Business Logic
│
▼
Guardrails
│
▼
Business Output
A system can use the “best” model and still perform poorly because the correct evidence never reaches it.
3. Production Evaluation
Offline datasets cannot reproduce every real user request. Production telemetry should therefore feed new failures back into the evaluation suite.
OpenAI's current evaluation best-practices guidance recommends eval-driven development, task-specific tests, comprehensive logging, automation where appropriate, and continuous incorporation of real-world feedback. It also warns against “vibe-based evals” and overly generic metrics. Evaluation is therefore a lifecycle, not a final QA milestone.
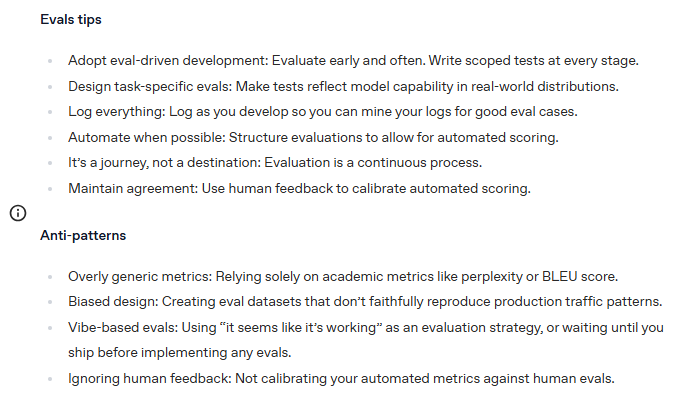
OpenAI’s current evaluation best practices guidance (Source: OpenAI)
Which AI Model Evaluation Metrics Should You Use?

Traditional Machine Learning
For classification:
| Metric | Best used when |
| Accuracy | Classes are reasonably balanced |
| Precision | False positives are costly |
| Recall | Missing a positive case is costly |
| F1 | Precision and recall both matter |
| AUC-ROC | Comparing ranking/classification performance across thresholds |
For regression, common measures include MAE, MSE, RMSE, and R². The important point is to connect the metric to operational cost. A five-percent prediction error may be acceptable in demand forecasting and unacceptable in a safety-critical application.
Read more: The Operational Impact of Manufacturing Downtime Cost
Generative AI and LLMs
Generative outputs need multidimensional scoring. Useful dimensions include:
- Correctness: Is the answer factually or task-wise correct?
- Groundedness: Is it supported by supplied evidence?
- Completeness: Did the response cover required information?
- Instruction following: Did it follow format and policy requirements?
- Relevance: Does it answer the actual question?
- Hallucination rate: How often does unsupported content appear?
- Safety: Does the output violate defined restrictions?
- Consistency: Does behavior remain stable across equivalent requests?
Google Cloud's current evaluation service distinguishes between computation-based metrics, such as ROUGE and BLEU, and model-based evaluation, including pointwise and pairwise scoring. Pairwise evaluation is especially useful when the practical decision is simply whether a new model, prompt, or tuning approach is better than the current baseline.
| Dimension | Model-based metrics | Computation-based metrics |
| How it works | Uses a judge model to assess a candidate model's output against descriptive evaluation criteria | Uses mathematical formulas to compare model outputs against a ground-truth or reference result |
| Typical judge / mechanism | Gemini for most use cases; MetricX or COMET can be used for translation tasks | Deterministic calculations such as string similarity, label matching, counts, or embedding distance |
| Ground truth required? | Optional in many cases | Usually required |
| Evaluation modes | Pointwise: score one model output against a rubric. Pairwise: compare two outputs and select the better one | Produces numerical scores based on predefined formulas |
| Best suited for | Qualitative or generative dimensions such as correctness, relevance, fluency, coherence, text quality, or preference between two outputs | Tasks with an objective reference or clearly measurable outcome |
| Common examples | Pointwise rubric scoring; pairwise model comparison; Gemini-as-a-judge; MetricX; COMET | Exact Match, ROUGE, BLEU, F1-score, Accuracy, Tool Name Match, embedding-based similarity |
| Typical output | A score or preference, plus an explanation/rationale for the assessment | A deterministic numerical score |
| Cost | Slightly higher, because another model performs the evaluation | Low |
| Speed | Slower | Fast |
| Strength | Can evaluate nuanced qualities that are difficult to express as exact formulas | Repeatable, objective, inexpensive, and easy to automate at scale |
| Typical use case | Compare two LLMs, compare prompts, assess whether tuning improved a baseline, or evaluate subjective response quality | Check exact answers, classification labels, translation similarity, structured outputs, or tool/function-call correctness |
Google further divides computation-based metrics into three groups: lexicon-based metrics such as Exact Match and ROUGE, count-based metrics such as F1, Accuracy, and Tool Name Match, and embedding-based metrics that measure similarity between generated output and reference in embedding space.
For model-based evaluation, Google supports two particularly useful modes. Pointwise evaluation is appropriate when you need an individual score for each model and can define a meaningful scoring rubric; Google suggests it for understanding production behavior, identifying weaknesses, establishing baselines, and finding areas for tuning. Pairwise evaluation is better when the goal is simply to determine which of two models, prompts, or configurations performs better—especially when defining a precise numerical rubric is difficult.
RAG Applications
A RAG system should separate retrieval from generation. Evaluate retrieval with metrics such as:
- Recall@K
- Precision@K
- Mean Reciprocal Rank
- NDCG
- Reranker quality
Then evaluate generated answers for correctness, grounding, citation quality, and completeness. This separation is essential. If the correct policy is never retrieved, repeated prompt tuning will not solve the root problem.
Computer Vision
Vision systems often require task-specific confusion matrices plus operational thresholds. A defect-inspection system may care more about critical false negatives than overall accuracy. The evaluation set should also represent real operating conditions such as different lighting, angles, equipment, seasons, product variants, and camera quality rather than only clean laboratory samples.
Five Practical AI Model Evaluation Methods

1. Deterministic Evaluation
Use exact matching, schema validation, numerical metrics, executable tests, or business rules whenever success can be defined objectively. Examples include:
- Correct classification label
- Valid JSON structure
- Required fields present
- SQL query executes correctly
- Tool argument satisfies schema
- Prediction error below threshold
Deterministic tests are cheap, repeatable, and easy to automate.
2. Human Evaluation
Human experts remain important when quality depends on nuance, domain judgment, or subjective usefulness. Use clearly defined rubrics rather than asking whether an answer “looks good.” Reviewers should know exactly what a score of 1, 3, or 5 represents. Human assessment is particularly useful for calibrating automated graders.
3. LLM-as-a-Judge
A stronger model can evaluate another model against a rubric. This makes large evaluation sets more practical, but judge models introduce their own biases. Where possible, validate judge agreement against expert human reviewers before trusting the scores at scale.
4. Pairwise Evaluation
Show an evaluator two outputs and ask which is better under a defined criterion. Pairwise testing is highly useful for comparing:
- Model A vs Model B
- Old prompt vs new prompt
- RAG vs no RAG
- Baseline vs fine-tuned model
It often produces more reliable decisions than forcing evaluators to assign arbitrary numerical scores.
5. Adversarial and Red-Team Evaluation
Normal examples test whether a system works. Adversarial tests examine how it fails. Include prompt injection, ambiguous instructions, malicious input, missing context, conflicting data, unusual formats, permission boundaries, and requests that should be refused.
NIST's September 2026 ARIA Evaluation Planning Manual explicitly combines model testing, red teaming, and user testing as three complementary elements of holistic AI-system evaluation. The three approaches answer different questions:
| Evaluation Method | How NIST Defines It | What It Reveals | Enterprise Example |
| Model Testing | Automated testing using pre-defined prompts selected by evaluators | Whether the AI consistently meets defined capability, safety, privacy, or reliability requirements across a controlled test set | Test 1,000 fixed customer-support questions for correctness, groundedness, policy compliance, and refusal behavior |
| Red Teaming | Human testers adversarially interact with the AI and dynamically react to its responses | Failure modes that fixed test sets may not anticipate, including unsafe behavior, policy bypasses, manipulation, or unexpected interaction paths | Ask testers to manipulate a maintenance assistant into recommending procedures that violate factory safety protocols |
| User Testing | Human testers interact with the AI in its intended context of use, followed by structured feedback or questionnaires | Whether the system remains useful, understandable, trustworthy, and effective under realistic usage | Give claims officers an AI assistant and measure task completion, errors, user confidence, and workflow friction |
NIST highlights an important trade-off between automated and human evaluation. Automated Model Testing is easier to scale, consistent, and repeatable, but relies on pre-specified prompts. Human testing is dynamic, can explore unanticipated interactions, and better captures realistic contexts of use.
This creates a useful layered evaluation model:
MODEL TESTING
"Does the system perform correctly
on what we know to test?"
│
▼
RED TEAMING
"How does the system fail when
someone actively pushes its boundaries?"
│
▼
USER TESTING
"What happens when real people use it
for the intended workflow?"
The distinction matters because passing one layer does not guarantee success at the next. A model can score highly on a fixed evaluation set yet expose an unexpected vulnerability during adversarial interaction. It can survive red teaming and still fail in production because users misunderstand the interface, over-trust the output, or use the system differently from how developers expected.
NIST therefore frames ARIA-style evaluation around a specific context of use and target concept, such as validity, safety, security, privacy, or explainability. Instead of asking whether an AI system is “good” in general, the evaluation should define what characteristic matters, in which sector, for which use case, and then choose the combination of testing methods needed to measure it.
For enterprise teams, the practical takeaway is: Model testing measures expected behavior. Red teaming searches for unexpected failure. User testing measures whether the AI actually works in the environment where people will depend on it.
A production-ready evaluation strategy should cover all three perspectives whenever the application's risk and business impact justify the additional testing.
Build an Evaluation Dataset That Resembles Production
The dataset is often more important than the evaluation framework.
A test set consisting only of easy examples creates misleading confidence. A useful evaluation dataset should represent both the normal traffic distribution and cases where failure matters most.
Build it from:
- Historical real-world requests
- Expert-created examples
- Production logs
- Known failure cases
- Edge cases
- Adversarial inputs
- Regulatory or policy-critical scenarios
- Synthetic examples used to fill clearly identified coverage gaps
Keep the final evaluation set separate from prompt and model optimization. Otherwise, teams gradually optimize for the test set instead of improving general performance.
This is increasingly important as public benchmark contamination becomes harder to avoid. The best enterprise defense is a private, continuously maintained evaluation set that mirrors the application's actual use.
Read more: What Is Intelligent Workflow Automation? A Complete Guide for Modern Businesses
A Practical AI Model Evaluation Pipeline

The evaluation process should resemble software testing: every important change should be measurable against the current production baseline.
A practical flow looks like:
Production / Expert Data
│
▼
Evaluation Dataset
│
├── Normal Cases
├── Edge Cases
├── Failure Cases
└── Adversarial Cases
│
▼
Candidate Model / Prompt / RAG
│
▼
Graders
│
┌──────┼────────┐
▼ ▼ ▼
Rules LLM Human
│
▼
Evaluation Report
│
├── Quality
├── Safety
├── Latency
└── Cost
│
▼
Release Gate
The release gate is important because model evaluation without an explicit decision threshold becomes reporting rather than engineering.
For example:
release_criteria:
answer_correctness: ">= 0.94"
groundedness: ">= 0.97"
critical_policy_violations: 0
p95_latency_ms: "<= 3500"
average_cost_per_task_usd: "<= 0.06"
regression_policy:
critical_metric_drop: 0
noncritical_metric_drop: "<= 2%"
Illustrative evaluation configuration.
The model with the highest correctness score may still lose if it doubles latency or triples operating cost for a negligible quality gain. Production model selection is a multi-objective optimization problem.
Read more: AI Automation vs RPA: Key Differences, Use Cases, and How to Choose
Evaluate the AI System, Not Just the Foundation Model
This becomes especially important with RAG and AI agents. Suppose an enterprise knowledge assistant scores only 78% answer correctness. That number alone does not identify the fix. A better diagnostic breakdown might show:
| Component | Result |
| Retrieval Recall@5 | 71% |
| Reranker success | 93% |
| Groundedness when correct evidence retrieved | 97% |
| Format compliance | 99% |
The model is probably not the main problem. Retrieval is. Fine-tuning or upgrading to a larger model may increase cost without solving the missing-context problem. The same principle applies to agentic systems. An agent can produce an excellent final answer while taking an unacceptable route to get there.
Anthropic's 2026 guide to evaluating AI agents emphasizes that multi-turn agents are harder to evaluate precisely because they call tools, modify state, and adapt through intermediate steps. Agent evaluations therefore need to inspect outcomes and trajectories rather than final text alone.

For an agent, evaluate:
- Task completion
- Correct tool selection
- Tool arguments
- Permission compliance
- Number of unnecessary steps
- Recovery from tool failures
- Escalation behavior
- Cost per successful task
- End-to-end latency
A successful final answer does not excuse an unsafe execution path.
Continuous Evaluation: What Changes After Deployment?
Passing a pre-production test suite is only the beginning.
Production introduces new data, user behavior, edge cases, provider upgrades, business-rule changes, and potentially model drift. The evaluation dataset should therefore evolve with the application.
A practical feedback loop is:
Production
↓
Logs + User Feedback
↓
Failure Analysis
↓
New Eval Cases
↓
Model / Prompt / System Improvement
↓
Regression Evaluation
↓
Release
This is why model evaluation belongs inside LLMOps or MLOps rather than being owned only by a QA team.
The 2026 AI Index illustrates why continuous testing matters: top models are improving quickly, but capability remains highly uneven. AI agents reached roughly 66% success on OSWorld while still failing around one in three structured tasks.
A model upgrade should therefore be treated like a software dependency upgrade: rerun the application's evaluation suite before switching production traffic.
Before Model Evaluation: Start With SotaTek's AI Readiness Assessment

A common mistake is to begin evaluating models before the organization has defined what success means. If the business problem, data, workflow, or ROI target is unclear, comparing ten models simply produces a more precise answer to the wrong question.
As part of SotaTek's AI Consulting Services, our AI Readiness Assessment evaluates whether the organization has the foundations required for a viable AI initiative. SotaTek's current AI service framework assesses business goals, data availability and maturity, infrastructure, internal capabilities, governance requirements, technical feasibility, and user-adoption needs before recommending an implementation path.
A readiness assessment should establish:
- Business outcome: What measurable problem is the AI system expected to solve?
- Use-case priority: Which workflows have the strongest combination of value and feasibility?
- Data readiness: Is representative and legally usable data available?
- Technical readiness: Can current systems expose the required APIs, data, and infrastructure?
- Evaluation criteria: What quality, latency, safety, and cost thresholds define success?
- Governance: What security, privacy, approval, or audit controls apply?
- Delivery readiness: Does the organization have the skills and ownership needed to operate the system?
The output is not a preferred model. It is a clearer AI strategy, prioritized use case, measurable success criteria, and a roadmap for validation through a PoC or production build.
This sequencing matters. Readiness defines what should be evaluated; model evaluation determines which technical approach can meet that requirement.
Read more: Top 10 AI Development Partners in Vietnam for 2026
How SotaTek Approaches AI Model Evaluation
SotaTek treats model evaluation as part of the AI development lifecycle rather than a final benchmark report. Our current AI engineering capability includes prompt and context optimization, accuracy and hallucination testing, model comparison and benchmarking, guardrails, output validation, performance monitoring, drift detection, and continuous optimization.
A typical engagement moves through four stages:
- Define the task and business threshold. Decide what the AI must achieve and which failures matter most.
- Build a representative evaluation set. Include normal traffic, edge cases, critical cases, and known failures.
- Compare system configurations. Test models alongside prompts, retrieval, tooling, latency, and cost.
- Operationalize evaluation. Turn high-value tests into release gates and continuously add production failures to the suite.
The objective is not to find the model with the most impressive benchmark profile. It is to find the least complex, economically viable system that reliably clears the business requirement. For manufacturing, that might mean optimizing critical-miss rate and inference speed. For financial services, auditability and false negatives may dominate. For enterprise knowledge systems, retrieval recall and groundedness may matter more than generic reasoning scores.
Read more: Digital Transformation in Banking: Redefining the Future of Finance
AI Model Evaluation Checklist
Before approving a model or AI system for production, ask:
- Is the evaluation dataset representative of real usage?
- Are difficult and high-risk cases deliberately included?
- Are business-specific success thresholds defined?
- Are we measuring the whole application rather than only the model?
- Have quality, safety, latency, and cost all been tested?
- Are automated graders calibrated against human judgment?
- Have we tested adversarial and failure scenarios?
- Can we identify regressions after a model or prompt update?
- Do production failures become new evaluation cases?
- Is there a clear release gate and accountable owner?
If several answers are no, the organization is still experimenting rather than operating a mature evaluation process.
Conclusion
AI Model Evaluation is becoming more important precisely because models are becoming more capable. When multiple frontier models perform strongly on broad benchmarks, the enterprise advantage comes from understanding which model performs best inside a specific workflow, with specific data, under specific reliability and economic constraints.
The right approach moves from benchmark comparison to task-specific evaluation, then to system-level testing and continuous production monitoring. It evaluates not only correctness, but retrieval, safety, latency, cost, tool behavior, edge cases, and business outcomes.
The goal is not to prove that an AI model is intelligent. The goal is to produce enough evidence to justify trusting it with a real business process.
If your organization is evaluating models, planning an AI PoC, or still determining whether its data and systems are ready for AI, contact SotaTek's AI team to assess AI readiness, define the right evaluation framework, and build a production path around measurable business outcomes.

 https://www.sotatek.com/
 (+84)2466585248




